
The service works beautifully after a restart. Requests are fast, dashboards look calm, and nothing in the error log seems unusual. Then, hours or days later, latency rises, memory usage keeps climbing, and eventually a container is restarted or a server runs out of room.
This is a familiar production problem because a memory leak rarely announces itself with one obvious broken line of code. It is usually a pattern: the application retains a little more data after each request, task, connection, or screen visit.
Memory leaks matter because they turn healthy capacity into a shrinking budget. They can cause slowdowns, garbage-collection pressure, failed deployments, crashes, and incident-response work that distracts teams from planned engineering.
Finding one is less about guessing and more about forming a measurable hypothesis: what is growing, when does it grow, and why is the runtime still able to reach it?
🧠 What a Memory Leak Actually Is
A memory leak occurs when a program keeps memory allocated or reachable after that memory is no longer useful. The application may still function, but its memory footprint grows beyond what its real workload requires.
In languages with manual memory management, a leak often means code allocated memory and never released it. In garbage-collected languages, the usual issue is different: an object remains reachable through a reference, so the garbage collector correctly decides it cannot reclaim it.
The key word is unnecessary. A cache, a loaded dataset, or a connection pool can legitimately use memory for a long time. It becomes a leak when retained data no longer serves a defined purpose or has no effective limit.
📈 Why Rising Memory Does Not Always Mean a Leak
A growing memory graph is evidence worth investigating, not a verdict. Runtimes often reserve memory from the operating system and keep it available for future allocations rather than immediately returning it after garbage collection.
Traffic growth, a larger working dataset, warm-up behavior, batch processing, and caching can all create an upward trend. A process may stabilize at a higher level once it has warmed up.
What separates a likely leak from normal behavior is a repeated pattern: after equivalent work completes and cleanup has had a chance to run, the memory baseline continues to rise. Compare like with like rather than judging one isolated spike.
🗂️ Distinguish Heap, Stack, Native Memory, and Resources
“Memory” is not one thing. A useful investigation begins by identifying which kind is increasing, because each kind points toward different tools and causes.
| Area | What it commonly contains | Typical failure pattern |
|---|---|---|
| Managed heap | Objects controlled by a runtime or garbage collector | Collections, caches, listeners, or object graphs keep growing |
| Native memory | Runtime internals, C/C++ allocations, buffers, libraries | Native extension or buffer allocation is not released |
| Stack | Call frames and local execution state | Usually excessive recursion or too many threads, not a classic leak |
| Operating-system resources | Files, sockets, database cursors, handles | Resources remain open and eventually exhaust system limits |
A heap snapshot cannot fully explain native allocations or file-descriptor exhaustion. Check the operating system, runtime metrics, and application behavior together.
🔍 Start with a Reproducible Symptom
Vague reports such as “the app gets heavy” make debugging expensive. Write a short problem statement that names the process, environment, observed metric, time window, workload, and user impact.
For example: a hypothetical API process grows in resident memory after every import job, while request volume remains steady. The useful next question is whether the managed heap, native buffers, or open resources grow after each completed import.
Capture a baseline shortly after startup, then record observations at consistent points in the workload. Reproducibility turns a production mystery into an experiment.
📊 Read Memory Graphs as Trends, Not Single Points
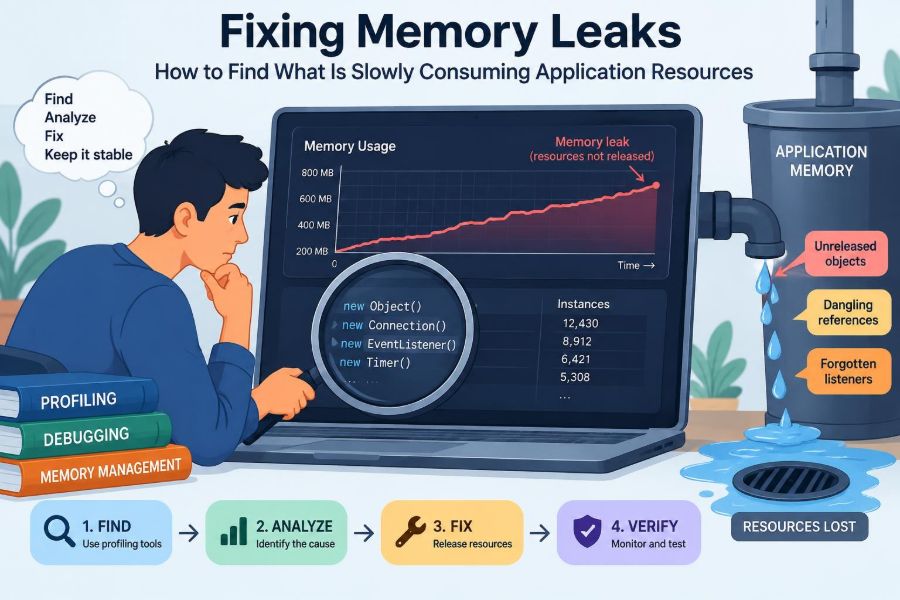
Memory charts often resemble a sawtooth: allocations push usage upward, then garbage collection drops it. That shape is normal when the post-collection floor remains roughly stable.
A warning sign is a rising floor. If each collection frees some memory but the lowest point steadily climbs after identical cycles, long-lived objects are accumulating.
Also compare memory to meaningful workload counters: requests completed, messages consumed, active users, files processed, or jobs run. A memory increase proportional to an intentionally growing dataset may be expected; a rise per completed request usually deserves scrutiny.
🧪 Create a Controlled Workload
Production telemetry can reveal the pattern, but a controlled test is often the fastest path to a cause. Run the smallest repeatable sequence that appears to increase memory, such as opening and closing a page, processing one file, or calling one endpoint many times.
Use realistic inputs. A leak that only appears with large payloads, failed requests, or slow clients may not reproduce with a happy-path test.
Run enough iterations to separate noise from accumulation. Between rounds, allow asynchronous cleanup and garbage collection to occur naturally where possible; forcing collection can be informative in some runtimes, but it should not replace observing normal application behavior.
🧭 Define the Expected Object Lifetime
Before opening a profiler, state what should survive each operation. A request object should generally disappear after its response is complete. A session may live longer. A global configuration object may intentionally live for the process lifetime.
This simple exercise reveals design questions that tools cannot answer: should this cache be bounded, should this subscription end, and who owns this resource?
Leaks are often lifetime mismatches. An object created for a short-lived task accidentally becomes attached to a long-lived manager, singleton, thread, or global registry.
🪢 Follow Reachability, Not Just Allocation Volume
Allocation profiling shows where objects are created. That is useful, but high allocation alone does not prove a leak: many temporary objects can be allocated and reclaimed efficiently.
Retention analysis asks the more decisive question: why is a particular object still alive? In a garbage-collected runtime, a path from a GC root—such as a global variable, active thread, static field, or live stack frame—explains that reachability.
Look for the chain that should have been broken. An event emitter holding a callback, which closes over a view model, which references a large result set, is more actionable than a report saying “result-set objects are large.”
📸 Use Heap Snapshots as Before-and-After Evidence
A heap snapshot records objects currently retained in a process. Take one at a known quiet baseline, execute the controlled workload, let work settle, then take another snapshot.
Compare object counts and retained sizes, especially for types that grow across repeated runs. Retained size estimates how much memory could become collectible if an object were released, including data reachable only through that object.
Snapshots are a moment in time, not a complete story. A growing type may be a symptom rather than the owner of the bad reference, so inspect reference paths and dominators before editing code.
🏛️ Understand Dominators and Retaining Paths
An object dominates another when the dominated object cannot be reached without passing through it. Dominator views help locate containers or owners whose release would free a substantial part of the heap.
A retaining path traces from a retained object back toward a root. It may reveal a map in a singleton, a pending promise, a listener list, or a thread-local value holding the data alive.
Do not assume the first large object is wrong. A large array might be retained because a small metadata entry in a global map points to it. The map entry, its missing expiry rule, or its absent removal may be the real defect.
🧱 Inspect Collections That Only Grow
Maps, dictionaries, arrays, sets, queues, registries, and in-memory indexes are common leak locations because they provide convenient long-lived ownership. Every insertion needs a removal, expiry, replacement, or size policy.
Audit collections that sit on application-wide objects. Ask what key is used, when entries are removed, what happens on errors, and whether unusual inputs create unique keys indefinitely.
- Request tracking maps should remove entries on success, timeout, cancellation, and failure.
- Job queues should acknowledge or discard completed work according to their semantics.
- Session and tenant caches need expiration and capacity controls.
- Debug registries should not quietly remain enabled in production.
⚡ Unsubscribe Event Listeners and Observers
Event-driven code creates relationships that are easy to overlook. If a long-lived publisher stores a callback, the callback—and anything it captures—can remain alive until it is removed.
This appears in browser interfaces, message consumers, reactive streams, server-side event emitters, and desktop applications. Repeatedly mounting a component or starting a job without disposing its subscription can retain one object graph per cycle.
Pair registration with cleanup in the same abstraction when possible. A component’s teardown, a request’s finalization block, or a scoped subscription helper makes ownership visible instead of relying on callers to remember it.
🧵 Watch Threads, Tasks, and Async Closures
Asynchronous work can retain data longer than expected. A pending task may capture a request, a response buffer, or a service object until it completes, times out, or is cancelled.
Unbounded task queues and stalled futures are especially dangerous because they combine retained payloads with delayed completion. Thread-local storage can also retain values for the lifetime of a pooled worker thread unless it is cleared.
Set cancellation and timeout behavior deliberately. When a task is no longer useful, ending it promptly is both a correctness decision and a memory-management decision.
🧰 Treat Caches as Product Features, Not Convenient Maps
A cache is intentional retained memory, so it needs an explicit contract. Define what is cached, why it is worth caching, its maximum size or memory budget, its expiration rule, and how it behaves under pressure.
An unbounded cache can look exactly like a leak from the outside. Whether it is called a leak or a design flaw matters less than whether it can eventually consume available capacity.
Choose eviction policies based on access patterns, not habit. Time-based expiry can serve changing data; size limits protect capacity; weak references can help in particular runtimes but do not replace a policy, because collection timing is not a dependable cache-control mechanism.
🔌 Close Files, Sockets, Cursors, and Handles
Some leaks are not primarily heap leaks. A file descriptor, network socket, database cursor, graphics object, or operating-system handle may remain open even if the wrapper object itself is small.
Symptoms include “too many open files,” inability to create new connections, slow failures under load, or a growing handle count. Garbage collection may eventually finalize some wrappers in certain environments, but cleanup timing is not reliable enough for scarce resources.
Use language-appropriate scoped cleanup constructs, such as deterministic disposal or structured resource blocks. Ensure exceptional paths close resources too, not just the successful path.
🗃️ Be Suspicious of Large Buffers and Payload Copies
Large payloads magnify small retention mistakes. Keeping one uploaded file, serialized response, image buffer, or parsed document alive can consume more memory than thousands of ordinary objects.
Copies are another source of surprises. A transformation pipeline may hold the original bytes, a decoded representation, a compressed form, and a logging copy at once. Peak memory can become a capacity problem even when every object is eventually released.
Stream large inputs when practical, impose request-size limits appropriate to the product, and avoid retaining full payloads in logs, error objects, or retry queues without a clear policy.
🌐 Find Browser and Front-End Leaks
In client applications, the visible symptom may be a tab that becomes slower after repeated navigation. Detached DOM nodes, retained component state, timers, event listeners, and subscriptions are frequent causes.
Test a route or modal with a repeatable cycle: open it, interact with it, close it, then repeat. Take heap snapshots after the interface is closed, because objects needed while the screen is active are not evidence of a leak.
Framework lifecycle hooks help only when cleanup code is actually connected to them. Clear intervals, cancel pending work where supported, remove manually added listeners, and inspect closures created by callbacks.
☕ Investigate Managed-Runtime Leaks Carefully
In runtimes such as Java, .NET, JavaScript, Python, Ruby, and Go, garbage collection handles unreachable memory. It cannot reclaim objects that application references still make reachable.
Useful runtime-specific tools differ, but the reasoning is consistent: inspect heap growth, compare snapshots or histograms, find retaining paths, and correlate retained types with workload behavior.
Do not respond by repeatedly forcing garbage collection or increasing the heap limit. Those actions may temporarily change symptoms, but they do not remove an unintended ownership path. A larger limit can buy diagnostic time; it is not a repair.
🧩 Diagnose Native and Interoperability Leaks
Managed heap metrics can look healthy while process memory rises. Native libraries, memory-mapped data, direct buffers, image codecs, database drivers, and foreign-function interfaces may allocate outside the managed heap.
Use operating-system-level process metrics and any allocator or runtime diagnostics available in your platform. Then narrow the issue by disabling optional integrations, reducing input size, or testing the suspected library in a small isolated program.
Ownership rules are crucial at language boundaries. Establish which side allocates, which side releases, and when release must occur. Ambiguous ownership is a common route to both leaks and unsafe double-free errors in manually managed environments.
🧯 Include Error, Retry, and Cancellation Paths
A cleanup routine that works only on success is incomplete. Real systems encounter timeouts, partial writes, malformed input, cancellation, retries, and exceptions—and those paths may bypass normal teardown.
Review code with a simple question: after every early return or failure, who releases each acquired resource and unregisters each temporary reference? Structured cleanup reduces the number of places where that answer can be forgotten.
Retry logic deserves particular attention. Retaining failed payloads for diagnostics or replay can be valid, but it needs bounds, expiration, and backpressure so a downstream outage does not create an unlimited in-memory backlog.
🧬 Use Load Tests to Reveal Slow Accumulation
A unit test that runs an operation once rarely exposes a leak. Add targeted endurance tests that repeat realistic lifecycle operations and observe whether memory returns near a stable range after settling.
These tests should avoid brittle assertions about exact byte counts, since runtimes and environments vary. Instead, test for behavior: no unbounded retained-item count, no continuously rising baseline across controlled cycles, and no resource count that grows without release.
Load testing also identifies capacity issues that are not leaks, such as temporarily high allocation rates or oversized concurrent buffers. Both can require design changes, even though their fixes differ.
📡 Monitor Leading Indicators in Production
Production monitoring should connect resource signals to workload signals. Process memory alone is useful, but it becomes far more diagnostic when viewed alongside request rate, queue depth, active connections, restarts, garbage-collection activity, and resource-handle counts.
Alert on sustained trends and risk to configured limits rather than every ordinary fluctuation. A rapid climb toward a container memory limit needs a different response from a stable process that simply reserves memory after startup.
Record deployment versions and feature changes on dashboards. A trend that begins immediately after a release gives investigators a valuable boundary for comparison.
🚑 Mitigate Safely While You Investigate
A restart may restore service, and scheduled restarts can sometimes reduce immediate operational risk. They are a mitigation, not evidence that the underlying problem has been fixed.
Other temporary controls include lowering concurrency, bounding queues, reducing cache limits, rejecting oversized work, rolling back a recent change, or isolating a problematic workload. Each has product trade-offs, so document what was changed and why.
Preserve diagnostic evidence before recycling a process when safe to do so. A heap dump, allocation profile, relevant metrics, and a request sample can prevent the next incident from starting at zero knowledge.
🛠️ Make the Fix Small, Explicit, and Verifiable
A good fix changes ownership or lifetime directly: remove an entry in all completion paths, dispose a subscription, cap a cache, close a cursor, or stop capturing a large object in a background callback.
Avoid broad changes that merely obscure the symptom, such as clearing unrelated global state or adding arbitrary periodic garbage collection. Such changes can introduce data loss, latency spikes, or new races.
After the patch, rerun the same controlled workload and compare it with the original evidence. Confirm both that retained memory stabilizes and that the feature still behaves correctly under success, failure, and cancellation.
📝 Add Regression Tests and Ownership Documentation
A leak fix can quietly regress when later refactoring changes a callback, cache, or lifecycle boundary. Add a focused regression test where practical, particularly for repeated component mounting, job processing, or resource acquisition.
Document non-obvious ownership rules near the code. A short note such as “caller must close this stream” or “registry entries expire after completion” can prevent future ambiguity.
For shared infrastructure, expose safe APIs. A cache wrapper with mandatory limits or a subscription helper that returns a disposer makes the correct pattern easier than the leaky one.
🚫 Avoid Common Investigation Traps
Several habits delay resolution:
- Chasing the largest object first: inspect what retains it before assuming it is at fault.
- Testing only a fresh process: slow leaks need repeated operations and settled measurements.
- Equating allocation with leakage: temporary allocation is normal when reclamation works.
- Relying on finalizers: nondeterministic cleanup is unsafe for scarce resources.
- Calling every cache a leak: evaluate its purpose, bounds, and eviction behavior.
- Fixing only the happy path: errors and cancellations often hold the missing cleanup.
The goal is not to make memory usage perfectly flat. It is to make resource growth understandable, bounded, and appropriate to the work being performed.
🤝 Build Memory Awareness into Code Review
Memory reliability improves when teams discuss lifetime during normal development rather than only during incidents. Code review questions can be concrete: who owns this object, when does it end, what happens on failure, and is this collection bounded?
Pay extra attention to long-lived services, global state, callback registration, background workers, queues, and integrations with native resources. These are boundaries where accidental retention has outsized effects.
Observability is part of the design as well. Metrics for cache entries, active tasks, queue depth, and open resources provide earlier clues than a crash report.
✅ The Core Principle: Make Lifetimes Deliberate
Memory leaks are rarely solved by one universal tool. Profilers, snapshots, logs, and dashboards help locate symptoms, but the lasting solution comes from understanding object ownership and resource lifetime.
Measure a repeatable pattern, identify what remains after useful work ends, trace why it is still reachable or open, and change the code so cleanup has a clear owner. Then verify the same workload no longer creates unbounded growth.
That approach applies whether the retained thing is a JavaScript component, a Java collection, a .NET event handler, a Python task, a native buffer, or a database cursor. The technology changes; the lifetime question does not.
The most reliable way to prevent and fix memory leaks is to make every long-lived reference, cache entry, task, and resource have an intentional, bounded lifetime. With that habit, slowly growing memory becomes a diagnosable engineering problem rather than an unpredictable production mystery. 🧠🔧📈