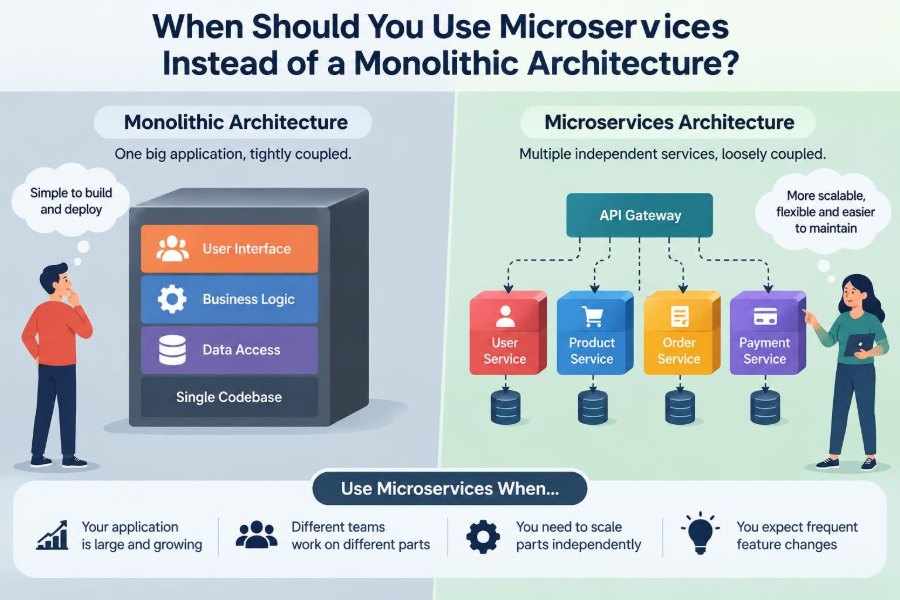

A product team starts with a straightforward application: one codebase, one deployment pipeline, and one database. It is easy to run locally, easy to explain to new developers, and fast enough to change while the product is still finding its shape.
Then the product grows. Checkout releases are delayed because reporting changes are unfinished. A surge in image processing affects the whole site. Teams step on one another’s code, and a deployment for a small feature carries the risk of changing everything.
At this point, microservices often sound like the obvious answer. Split the application into smaller services, let teams deploy independently, and scale only the busy parts. But that move also replaces in-process method calls with networks, operational work, and new kinds of failure.
The useful question is not whether microservices are modern or monoliths are outdated. It is whether the specific problems your organization has are problems that service boundaries can genuinely solve.
🧱 Start with what a monolith actually is
A monolithic architecture is an application deployed as one unit. Its modules may handle accounts, billing, search, and notifications, but they run in the same process or release together as one system.
That does not mean its code must be tangled. A well-designed monolith can have clear internal modules, explicit interfaces, and strong tests. The defining feature is deployment and runtime structure, not poor code quality.
For many products, this simplicity is a major advantage: calls between modules are local, debugging has fewer moving parts, and a developer can understand a request without tracing it across several deployed applications.
🧩 Define microservices without the marketing
Microservices are small, independently deployable services organized around business capabilities. A service typically owns a focused responsibility, such as inventory availability or customer notifications, and communicates with other services through network interfaces.
“Micro” should not be interpreted as “tiny.” A service that is too small creates excessive coordination. The goal is an independently understandable and changeable unit with a coherent purpose, not the smallest possible repository.
Each service usually has its own runtime configuration, monitoring, deployment process, and often ownership of its data. Those properties create independence, but they also create substantial operational responsibilities.
⚖️ Treat the choice as a trade-off, not an upgrade
Microservices do not automatically improve an architecture. They exchange some monolith problems for distributed-systems problems: latency, partial outages, duplicate messages, versioned contracts, and complicated diagnosis.
A monolith can make organizational coordination visible because people must work in one codebase. Microservices can reduce that coordination at carefully chosen boundaries, but only if teams can truly own those boundaries.
| Concern | Monolith often favors | Microservices can favor |
|---|---|---|
| Development | Fast early iteration and simple local setup | Independent work in stable domains |
| Deployment | One release process | Separate release cadence per service |
| Operations | Fewer running components | Targeted scaling and isolation |
| Failures | Fewer network failure modes | Containment when boundaries are designed well |
| Data | Simple transactions and queries | Autonomy where data ownership is clear |
🌱 Prefer a monolith when the product is still changing shape
Early products often have uncertain workflows, shifting terminology, and features that cut across many parts of the business. In that environment, rigid service boundaries can turn a simple product decision into a cross-service redesign.
A modular monolith lets a small team learn quickly. If an “order” turns out to be more like a reservation, developers can revise code and data together without negotiating several APIs or synchronizing releases.
Use the architecture that makes learning inexpensive. Premature separation can preserve assumptions that the business has not yet validated.
👥 Look for teams that need genuine autonomy
Independent deployment matters most when multiple teams repeatedly need to change separate areas of a system. If the payments team can release payment logic without waiting for the catalog team, a service boundary may remove a real bottleneck.
Team autonomy is more than separate task boards. A team needs the skills and authority to build, test, deploy, monitor, and support its service. If every production change still depends on the same central group, separate services may only add handoffs.
Conway’s Law is a useful observation here: software structures often reflect communication structures. Aligning a service with a durable team can work; drawing boundaries around temporary project assignments usually does not.
🚦 Notice deployment coupling before splitting code
A common signal is repeated deployment coupling. Perhaps a change to pricing must always be released alongside promotions, or a small notification update requires retesting an unrelated and risky subsystem.
First ask why they are coupled. The reason may be tangled code, shared data, missing tests, or an overly broad release process. Some of those problems can be fixed inside a monolith.
Split into services when the coupling reflects a stable business boundary and independent releases would be valuable. Do not split merely because the current build takes too long; build performance is often a tooling problem.
📈 Separate uneven scaling from general growth
Traffic growth alone is not a reason for microservices. A monolith can be replicated horizontally, cached, tuned, and placed behind a load balancer. Many applications run effectively this way.
Microservices become more compelling when one workload has dramatically different resource needs. For example, a hypothetical marketplace might require CPU-heavy image conversion during seller uploads while its order API remains mostly database-bound.
Separating image processing lets the team scale workers without multiplying every part of the application. That benefit is strongest when the workload can be isolated cleanly and communicates through an asynchronous job or event.
🛡️ Use boundaries to limit meaningful failure blast radius
A blast radius is the scope of harm caused by a fault. If generating recommendations consumes excessive resources, isolating that capability may protect checkout and account access.
However, a network boundary does not automatically contain failures. If checkout synchronously waits for recommendations, an outage can still spread. Timeouts, fallback behavior, capacity limits, and sensible dependencies are what create resilience.
Choose services where degraded behavior is acceptable and explicit. A storefront might show fewer recommendations; it should not silently accept an order whose payment status is unknown.
🏢 Identify stable business domains
Good service boundaries usually follow business concepts rather than technical layers. “Inventory,” “shipping,” and “identity” may be coherent domains. “Controllers,” “database access,” and “email utilities” are usually implementation layers, not independently valuable services.
Domain-driven design calls a meaningful boundary a bounded context: a place where terms and rules have a consistent meaning. “Customer” in marketing may mean a subscriber, while in billing it may mean a legal account holder.
Different meanings are a clue that separate ownership could reduce confusion. The boundary is not proven by a diagram; it is proven by whether the rules, language, and rate of change remain coherent over time.
🗣️ Watch for conflicting language and rules
When one concept means different things to different teams, forcing a universal model can create fragile code. For instance, a “product” in a catalog may be a description and price, while fulfillment needs package dimensions and warehouse handling constraints.
Separate services can allow each domain to model the concept for its own purpose. They then exchange intentionally limited information rather than sharing one oversized object with dozens of fields.
This is valuable only when the distinction is real. Creating separate “product services” for minor naming differences can make ordinary changes unnecessarily expensive.
🗃️ Give each service clear data ownership
A microservice needs authority over the data that supports its rules. If the order service can directly rewrite inventory tables, ownership is blurred and future changes require hidden coordination.
In the strongest form, services use separate databases. In practice, a shared database may be a temporary migration step, but direct cross-service writes should be treated as a warning sign.
Data ownership does not mean secrecy. Services can publish events, offer query APIs, or maintain read models for other needs. It means one service defines how its authoritative records are changed.
🔄 Accept that distributed transactions are different
Inside a monolith with one database, a transaction can often update an order, reserve stock, and record payment atomically. Across services, one global transaction is frequently impractical or undesirable because it couples availability and implementation choices.
Instead, teams use workflows such as a saga: each service completes a local action, reports the outcome, and compensating actions handle failure where appropriate. An inventory reservation may be released if payment later fails.
This approach demands careful product decisions. Some actions cannot be safely undone, and users need clear states such as pending, confirmed, or canceled. If the business requires strict instantaneous consistency across many areas, a monolith may remain simpler.
⏳ Design for eventual consistency
Eventual consistency means different parts of the system may temporarily show different views of a change, then converge after messages are processed. A shipping dashboard might briefly lag behind an order confirmation.
That delay is acceptable only when users and business processes can tolerate it. A visible “processing” state is often better than pretending a distributed update is immediate.
Before adopting services, write down which facts must be current at the moment of a decision. Stock availability during a purchase may need stronger coordination than a customer’s marketing profile.
📨 Make asynchronous communication intentional
Events and queues can decouple services. An order service can publish OrderPlaced, while email, analytics, and fulfillment react independently. This avoids making the customer wait for every downstream activity.
But asynchronous systems require reliable handling. Consumers must tolerate duplicate delivery, messages can arrive late or out of order, and failed work needs a route for investigation or retry.
- Use idempotency so repeating a message does not repeat a charge or shipment.
- Include enough context for consumers without exposing unnecessary internal data.
- Record failures with correlation information so they can be traced.
- Define who owns a message contract and how it evolves.
🌐 Understand the cost of synchronous calls
A local function call is fast and normally either returns or throws immediately. A remote call can be slow, unavailable, or successful on the server while its response is lost on the network.
A request that calls five services in sequence accumulates latency and failure risk. This is sometimes called a distributed monolith: components are separately deployed, yet they cannot operate or release independently.
Keep synchronous dependencies few and purposeful. Set timeouts, avoid unbounded retries, and decide what the user experience should be when a nonessential dependency fails.
🔍 Invest in observability before complexity arrives
With one application, logs and metrics are often enough to follow a request. With services, a single customer action may cross gateways, workers, databases, and queues.
Observability is the ability to infer what a system is doing from outputs such as logs, metrics, traces, and health signals. Distributed tracing uses a shared correlation identifier to connect work across service boundaries.
Do not wait for an incident to add this foundation. Teams need searchable structured logs, useful dashboards, alerting tied to user impact, and an understandable way to trace an order or request end to end.
🧰 Count the platform work honestly
Microservices need more than application code. They need automated deployment, secret management, service discovery or routing, configuration practices, monitoring, access controls, and ways to manage incidents.
A platform team is not mandatory, but someone must provide and maintain these capabilities. If each feature team invents its own deployment scripts and logging conventions, autonomy becomes inconsistency.
Small organizations can operate services successfully with managed infrastructure and disciplined conventions. They should still budget for ongoing operations rather than treating infrastructure as a one-time migration task.
🔐 Expand your security model with every service
Each service adds credentials, network paths, software dependencies, and administrative surfaces. A request that once stayed inside a process may now need authentication and authorization across a network.
Use least-privilege access: a notification service should not hold credentials that can alter payment records. Encrypt traffic where appropriate, rotate secrets, and audit sensitive actions.
Security boundaries should match risk, not architecture fashion. Breaking a monolith into many services without consistent identity and access management can increase exposure instead of reducing it.
🧪 Rethink testing across service boundaries
Unit tests remain useful, but service systems also need contract tests, integration tests, and a small number of end-to-end tests. A contract test verifies that a provider and consumer agree on an API or event format.
End-to-end tests reveal important workflow failures, yet relying on them for all confidence makes feedback slow and failures hard to diagnose. Favor many focused tests close to the code and targeted tests across real boundaries.
Test failure cases as seriously as happy paths: delayed events, unavailable dependencies, duplicate messages, and incompatible client versions are ordinary distributed-system conditions.
📦 Plan API and event evolution
Once another service consumes an interface, changing it becomes a compatibility decision. Removing a field, renaming an event, or altering validation can break a consumer that deploys on a different schedule.
Prefer additive changes when possible. Introduce a new field or version, allow consumers time to migrate, observe usage, and retire the old contract deliberately.
Documentation helps, but automation is stronger. Schema validation and contract checks can catch accidental incompatibilities before they reach production.
💸 Include coordination and operating costs
The price of microservices is not limited to cloud resources. Developers spend time tracing requests, maintaining pipelines, reviewing interface changes, responding to alerts, and coordinating incidents across ownership boundaries.
There may also be more environments, more data copies, and more network traffic. These costs can be worthwhile when they prevent larger delivery delays or availability problems, but they must be compared with the problem being solved.
A sensible business case names a concrete cost of the current design and a measurable operational or delivery improvement expected from separation.
🚫 Avoid the distributed monolith trap
A distributed monolith has many deployables but retains monolith-level coupling. Common symptoms include shared databases, lockstep releases, long chains of synchronous calls, and an inability to run a service without most others.
This design has the operational burden of microservices without much of their independence. It is often created by splitting code mechanically rather than identifying boundaries and redesigning interactions.
If a separation does not permit a meaningful independent decision—deployment, scaling, data ownership, or failure handling—keep it as a module until a stronger reason emerges.
🏗️ Build a modular monolith first when possible
A modular monolith keeps one deployment unit while enforcing internal boundaries. Modules expose defined interfaces, avoid reaching into each other’s persistence details, and make dependencies visible.
This is not indecision. It is a practical way to prove domain boundaries with lower operational cost. When a module later needs separate deployment or scaling, its existing interface makes extraction safer.
Techniques include separate packages, dependency rules, module-level tests, and explicit application services. The exact language and framework matter less than preventing casual cross-module access.
✂️ Extract one service through a deliberate seam
When a boundary is justified, avoid a large rewrite. Choose a capability with clear ownership, limited dependencies, and a manageable failure mode—such as report generation or document conversion.
The strangler pattern gradually routes selected behavior from the existing application to a new service. The old system remains in place while the new path earns trust through production use.
- Map the current data, callers, and business rules.
- Define the new service’s responsibility and contract.
- Move behavior behind an interface or routing layer.
- Transfer data ownership carefully and observe the new path.
- Remove obsolete code and dependencies rather than maintaining two permanent sources of truth.
📋 Use a decision checklist, not a trend checklist
Before splitting, ask questions that connect architecture to evidence. The answers do not need to be perfect, but vague optimism is not a design rationale.
- Is there a stable business capability with a clear owner?
- Do separate teams need to release it independently and often?
- Does it have distinct scaling, reliability, or security requirements?
- Can its data be owned without routine cross-service writes?
- Can users tolerate the consistency and latency trade-offs?
- Do we have deployment, monitoring, incident, and security practices ready?
- Would improving the monolith solve the problem more cheaply?
Several strong “yes” answers point toward service extraction. One weak pain point usually points toward targeted improvement inside the monolith.
🧭 Choose architecture by the problem in front of you
Use microservices when independent business domains, durable team ownership, distinct operational needs, and mature delivery practices reinforce one another. The architecture is most valuable when it enables autonomy that the product and organization can actually use.
Use a monolith when simplicity, rapid learning, transactional consistency, and a small team matter more than independent deployment. Improve its modules, tests, release process, and performance before assuming physical separation is required.
The best architecture can change as a product changes. Revisit the decision when evidence changes, not when a diagram starts to look unfashionable.
🎯 The core principle: earn every network boundary
A service boundary is a promise: separate teams can evolve a capability, operate it safely, and coordinate through a stable contract. Every such promise introduces costs in communication, data, testing, and operations.
Make that promise only when the resulting independence solves a concrete and recurring problem. A modular monolith is often the right starting point, and a carefully extracted service is often better than a wholesale migration.
Architecture succeeds when it makes the next set of product and operational decisions easier—not when it maximizes the number of deployable components.
Choose microservices when real autonomy and isolation outweigh distributed complexity; otherwise, keep the system simple and modular. That is a stronger strategy than treating either architecture as a badge of maturity. 🧩⚙️📈