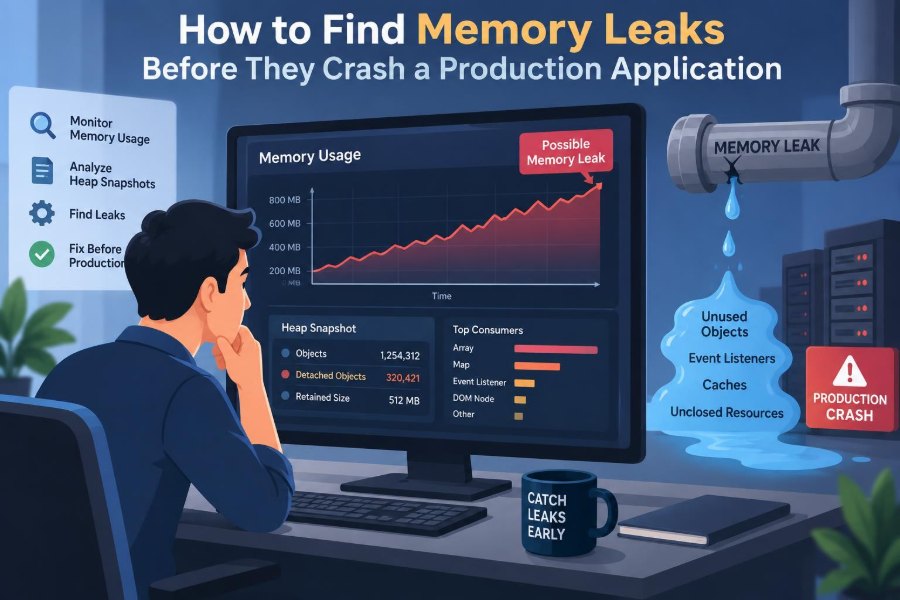

It is 2:00 a.m., and the application is not technically down. Requests are still completing. The error rate is low. Yet every few minutes, another instance restarts after the operating system or container platform kills it for using too much memory.
The first instinct is often to add more RAM, raise the container limit, or blame a recent traffic spike. Those actions may buy time, but they can also conceal the real problem: the process is retaining data it no longer needs.
Memory leaks are especially frustrating because they rarely announce themselves at startup. They emerge over time, under particular request patterns, after a background job runs repeatedly, or only when a long-lived connection stays open.
Finding them before production is not about guessing from a chart. It is about learning what healthy memory behavior looks like, instrumenting the application, and turning suspicious growth into a small, repeatable investigation.
🧠 Define a Memory Leak Precisely
A memory leak occurs when a program keeps memory reachable or allocated after that memory has stopped being useful. The practical symptom is memory that grows with time or workload and does not return to a stable range.
In garbage-collected languages, this usually does not mean the garbage collector is broken. It means a reference somewhere—such as a cache, listener, global collection, or closure—still tells the runtime that an object might be needed.
In manually managed environments, a leak can also mean allocated memory was never released. The diagnostic tools differ, but the operational question is the same: why is this memory still present?
📈 Separate Leaks from Normal Memory Growth
Not every rising line is a leak. A process may allocate memory while warming caches, compiling code, buffering work, or expanding an internal heap. It may then level off at a higher but healthy baseline.
A leak has a different shape: after equivalent work, the baseline keeps ratcheting upward. Look for growth across repeated cycles, not a single peak after deployment.
For example, a service that loads a fixed reference dataset may legitimately use more memory for its first hour. A service that adds 20 MB after every identical batch import has a stronger leak signal.
🗂️ Understand the Main Kinds of Memory
“Memory usage” is an umbrella term. A process can consume managed heap memory, native memory, thread stacks, memory-mapped files, graphics buffers, network buffers, or memory held by dependencies.
This distinction matters because a heap snapshot may look healthy while resident memory—the physical memory the operating system sees—continues to grow. Conversely, a large heap reservation may be normal even if live objects are stable.
| Memory area | Typical clue | Useful investigation |
|---|---|---|
| Managed heap | Live object count or retained size rises | Heap snapshot and allocation profiling |
| Native memory | Process memory rises without matching heap growth | Runtime-native diagnostics and library review |
| Thread stacks | Thread count climbs over time | Thread dump and executor inspection |
| Buffers or mappings | Large external allocations persist | Connection, file, and buffer lifecycle checks |
🔍 Start with the Right Production Signal
Track memory at the process and container level, not only inside application code. A runtime metric such as heap usage answers one question; the operating system’s resident memory answers another.
Useful companion signals include restart reasons, out-of-memory events, garbage-collection activity, request rate, queue depth, open file descriptors, connection count, and thread count. Correlation helps narrow the search without proving causation.
If memory rises only when open WebSocket sessions rise, investigate session lifetime. If it rises after a scheduled report, investigate the report pipeline before changing heap settings.
⏱️ Think in Workload Cycles, Not Clock Time
A graph over hours is useful, but leaks become clearer when aligned with meaningful units of work: requests served, messages processed, tenants imported, or jobs completed.
Suppose a worker processes 10,000 records every night. Record memory before the run, at its peak, and after cleanup and garbage collection have had an opportunity to run. Compare those points across several runs.
This approach distinguishes “the job needs 500 MB while active” from “the job leaves 50 MB behind each time.” The first may require capacity planning; the second requires code changes.
🧪 Make the Leak Reproducible
The fastest investigations create a controlled reproduction. Use representative input, execute the suspected operation repeatedly, and keep unrelated variables as stable as possible.
A simple pattern is: start the service, run a fixed scenario N times, wait briefly, collect metrics, and repeat. If the retained baseline grows after each round, you have transformed a production mystery into a testable behavior.
Do not expect every production leak to reproduce with toy data. Data shape often matters: unusually large payloads, many unique keys, failed requests, or disconnected clients may activate the faulty path.
📊 Establish a Healthy Baseline First
Before calling growth suspicious, measure a version that is known to behave acceptably or a fresh process handling ordinary traffic. Capture its startup memory, post-warmup range, and behavior under a standard load test.
A baseline gives reviewers a concrete comparison. “Memory feels high” becomes “after 50,000 messages, the candidate build retains substantially more live data than the reference build under the same scenario.”
Keep environment details with the result: runtime version, memory limits, input data, feature flags, and concurrency. Small differences can otherwise create misleading comparisons.
🧹 Know What Garbage Collection Can and Cannot Fix
Garbage collection reclaims objects that are no longer reachable. It cannot reclaim an object still referenced by a live map, callback registry, task queue, or parent object.
For diagnosis, an explicit collection cycle can sometimes clarify whether a temporary allocation burst has settled. It should not be used as a production “fix.” Forcing collection can hurt latency and only masks the reference path keeping objects alive.
The key question is not “why has the collector not run?” It is “what is retaining these objects after their useful lifetime?”
🧭 Read Retained Size, Not Just Object Count
Heap tools usually show shallow size and retained size. Shallow size is the memory used by an object itself. Retained size estimates how much memory would become collectible if that object and the objects it uniquely keeps alive disappeared.
A tiny map entry can have a huge retained size if it points to a request object, which points to a response buffer, which points to a large parsed document. That makes retained paths more revealing than raw object counts.
Focus on unexpected dominators: objects that sit near the top of the ownership graph and keep large subgraphs alive.
📸 Capture Comparable Heap Snapshots
A single heap snapshot is a photograph, not a story. Capture at least two snapshots after equivalent workload phases, then compare object classes, counts, and retained sizes.
Snapshots can contain sensitive application data: customer records, tokens, request payloads, and internal identifiers. Treat them as restricted artifacts, collect them carefully, and follow your organization’s data-handling rules.
For a suspected leak, capture after warmup and again after several repetitions of the scenario. Growth shared by both snapshots is often normal; growth unique to repeated work deserves attention.
🧵 Inspect Threads as Memory Owners
Every thread needs stack memory, and thread-local storage can keep data alive for as long as that thread exists. An unbounded thread-per-task design can therefore look like a memory leak even when the heap is not the primary issue.
Thread dumps reveal whether counts are stable and whether named worker pools are growing unexpectedly. Check custom executors, retry loops, background schedulers, and libraries that create their own threads.
Thread pools should be sized and bounded for the workload. A fixed pool is not automatically safe, but it prevents one common path to uncontrolled stack growth.
🧺 Audit Caches for Missing Boundaries
Caching improves performance by intentionally retaining data. A cache becomes leak-like when it has no meaningful size limit, expiration policy, eviction strategy, or invalidation rule.
The classic mistake is using user-controlled values as keys in a global map: request URLs, search terms, tenant IDs, or device identifiers. Unique input turns the cache into an ever-growing archive.
For each cache, answer four questions:
- What is the maximum number or weight of entries?
- When does an entry expire or get invalidated?
- Who owns the cache and observes its size?
- What happens during a traffic spike with mostly unique keys?
🔔 Remove Event Listeners and Subscriptions
Publish-subscribe systems are a frequent source of accidental retention. A publisher holds listener references; if subscribers never unsubscribe, the publisher may keep entire components, screens, sessions, or request contexts alive.
This appears in browser applications, message consumers, observables, application event buses, and callback-based APIs. The leak may only occur after navigation, reconnects, retries, or component replacement.
Make subscription ownership explicit. The code that creates a listener should define when and where it is removed, especially for objects with shorter lifetimes than the publisher.
🔒 Close Resources on Every Path
Database cursors, HTTP responses, file handles, compression streams, sockets, and native buffers often need explicit closure. Relying on eventual finalization or cleanup is unsafe for resources whose release affects memory, descriptors, or connection pools.
Use language-supported scoped cleanup patterns such as try/finally, try-with-resources, defer, or context managers. The important property is that cleanup runs on success, failure, cancellation, and early return.
resource = openResource()
try:
    process(resource)
finally:
    resource.close()
Leak tests should include error paths, because the happy path often closes resources while exceptions bypass cleanup.
📥 Bound Queues and Apply Backpressure
An unbounded queue retains work faster than consumers can process it. That is not always a traditional leak—the queued data is still logically pending—but it can crash a process just as effectively.
Backpressure is the mechanism that slows producers, rejects work, drops nonessential items, or otherwise prevents unlimited accumulation. It converts hidden memory growth into an explicit capacity decision.
Inspect message brokers, in-process queues, logging pipelines, asynchronous executors, and retry buffers. Track both item count and byte size because a few large payloads can be more dangerous than many small ones.
🪝 Watch Closures, Globals, and Static State
Long-lived globals and static fields are convenient roots in an object graph. Anything they reference can remain alive for the life of the process.
Closures can create the same effect more subtly. A callback intended to retain a small identifier may capture a much larger surrounding object, such as a request context or component tree.
When examining a retained path, look for these roots first: singleton services, module-level collections, static registries, thread locals, and callbacks stored by long-lived infrastructure.
🧩 Treat Dependency Code as Part of the System
A leak can be in application code, but dependencies also allocate buffers, pool objects, cache metadata, manage native resources, and create threads. A stack trace that leads into a library is not evidence that your code is innocent; your usage pattern may be incomplete.
Check release notes and known issue trackers when a leak appears after a runtime or library upgrade. Then verify configuration: connection pools, HTTP clients, serializers, image processors, and database drivers often expose limits that defaults do not set.
Upgrade carefully and reproduce the behavior. Changing several libraries and settings at once makes it hard to know which change resolved the issue.
🧱 Distinguish Fragmentation from Retention
Memory fragmentation occurs when free memory is split into regions that are difficult for an allocator to reuse efficiently. The process may retain a high resident-memory footprint even though live application objects are not growing.
This is different from object retention, but the visible symptom can be similar. If heap snapshots are stable while process memory remains high, investigate native allocators, large allocation patterns, runtime behavior, and memory-mapped resources.
Do not label every high resident-memory reading a leak. The remedy may involve allocation patterns, runtime tuning, or process recycling rather than removing an object reference.
🧮 Use Allocation Profiling for the Creation Side
Heap snapshots tell you what survived. Allocation profiling tells you where objects are being created. Both perspectives matter.
High allocation rate is not itself a leak: short-lived allocations may be collected efficiently. But it can expose an unexpected code path creating large request copies, repeated serialization buffers, or objects that later become retained.
Profile under realistic load and sample when possible. Full allocation tracking can add substantial overhead, so it is usually better suited to development, staging, or carefully controlled production diagnostics.
🧯 Add Safe Production Diagnostics
Production systems need observability before an incident. Export memory, garbage-collection, queue, thread, cache, and connection metrics with labels that make them actionable.
Set alerts on sustained trends and approach-to-limit conditions rather than only on a final out-of-memory crash. An alert should point an operator toward a runbook: capture a profile if safe, identify the affected workload, and preserve relevant logs and deployment information.
Diagnostic endpoints, heap dumps, and profilers can create load or expose sensitive data. Restrict access, rate-limit expensive actions, and document when each tool is safe to use.
🧪 Turn Leak Scenarios into Automated Tests
Unit tests rarely catch lifecycle leaks because they end too quickly. Add targeted integration or soak tests that exercise a flow repeatedly and assert that a relevant metric remains within an expected range after warmup.
Exact memory assertions are often brittle across machines and runtime versions. More robust tests compare trends: does live object count stabilize, does a cache remain bounded, does a subscription count return to zero, and does a queue drain?
A useful regression test is narrowly scoped. For example, create and destroy a client session hundreds of times, then verify no session objects remain registered in the test double or application metric.
🏗️ Design Ownership Before Writing Cleanup Code
Many leaks are ownership problems disguised as cleanup bugs. If nobody can answer who owns a resource, who may use it, and when its lifetime ends, cleanup will be inconsistent.
Model lifetimes explicitly: application-wide objects, tenant-scoped objects, request-scoped objects, task-scoped objects, and temporary values should not all be stored in the same long-lived container.
Dependency injection scopes, structured concurrency, and scoped resource APIs can make lifetime relationships visible in code. They do not prevent every error, but they reduce reliance on developers remembering invisible cleanup rules.
🚦Use Limits as Safety Rails, Not Cures
Container memory limits, maximum heap sizes, cache caps, connection limits, and queue capacities protect the wider system. They ensure one unhealthy instance cannot consume unlimited shared resources.
But a limit does not repair retention. If a service reaches the limit and restarts, it may still lose in-flight work, create restart loops, and obscure the underlying growth pattern.
Use limits to contain impact while investigating. Pair them with alerts and a restart policy appropriate for the service’s ability to recover safely.
🧭 Investigate One Retention Path at a Time
Large heap dumps can be overwhelming. Begin with the biggest unexpected retained group, trace its path to a garbage-collection root, and ask why that root should still own it.
A practical investigation sequence is:
- Confirm repeatable baseline growth under a known workload.
- Identify object types or non-heap resources that grow.
- Find the retaining owner, queue, cache, thread, or native allocation path.
- State the intended lifetime in plain language.
- Change the ownership or cleanup logic, then rerun the same scenario.
This keeps analysis evidence-driven. Avoid making several speculative fixes before measuring again.
🛠️ Recognize Common Failed Fixes
Restarting instances, increasing memory, calling garbage collection, and lowering traffic can reduce immediate pressure. None proves that the leak is solved.
Another weak fix is clearing every cache. That may remove useful performance behavior and leave the real retention path untouched. Instead, make the relevant cache bounded and observable, then test the eviction behavior.
Be equally cautious with “just upgrade it.” An upgrade can be correct, but it should be accompanied by a before-and-after reproduction and a rollback plan.
📝 Build a Memory Incident Runbook
When an alert fires, responders should not need to invent a debugging procedure while memory is disappearing. A runbook makes the first actions predictable and safer.
- Record deployment version, configuration, traffic level, and recent changes.
- Check whether growth is heap, native memory, threads, queues, or open resources.
- Compare affected instances with healthy instances handling similar work.
- Capture approved diagnostic artifacts before a restart when feasible.
- Reduce impact with safe limits, traffic controls, or replacement capacity.
- Preserve the workload details needed to reproduce the issue later.
Review the runbook after each incident. The best update is usually a missing metric, a clearer decision point, or a safer collection procedure.
🤝 Make Memory Behavior a Review Topic
Code review can catch many leaks before profiling is necessary. Ask whether a new collection is bounded, whether callbacks are unregistered, whether resources close during failures, and whether a background task has an exit condition.
These questions matter most around long-lived services and asynchronous code. A local variable usually dies with a function; a global registry, retry queue, and scheduler can silently outlive thousands of functions.
Teams benefit from discussing expected lifetime in pull requests: “This object is retained until the request completes” is clearer and more reviewable than “we will clean it up later.”
🎯 Choose Prevention Over Postmortem Guesswork
The core discipline is to treat memory as a lifecycle problem. Every retained object, buffer, connection, listener, and queued message should have a reason to exist and a condition under which it is released.
Measure the process from the outside, inspect the runtime from the inside, reproduce suspicious growth with repeatable workloads, and follow ownership paths rather than intuition. Some incidents will involve fragmentation, legitimate capacity needs, or dependency behavior rather than a conventional leak, so evidence matters.
A production crash is the last and least helpful signal. Stable baselines, bounded structures, cleanup-safe design, and trend-based monitoring allow teams to find growth while there is still time to understand it.
The most reliable way to prevent memory-leak outages is to make object and resource lifetimes observable, bounded, and testable long before memory reaches its limit. ⚙️📈🧠